Intel is preparing to address a major hole in its product line, high-performance desktop processor market. Intel has let the lineup fall behind and give ground to AMD, but it is looking to change that.
Speaking during Intel’s third quarter 2026 earnings call, CFO David Zinsner acknowledged that the company’s existing desktop portfolio has gotten a bit long in the tooth at the high end of the market. Nova Lake, expected to arrive in 2027, is intended to close that gap with AMD’s Ryzen line.
“The important aspect of Nova Lake is we’ve had a bit of a hole in our portfolio for high-end desktop, and Nova Lake filled in that gap,” Zinsner told analysts on the call.
Intel has a high-end part, the Core Ultra 9 285K, which was introduced in late 2024. Two years is a generation or two in semiconductor sales and AMD has since shipped newer chips.
Intel still has a lead in market share, according to Mercury Research. It puts the desktop split between Intel and AMD at 2:1. The difference is the markets. Intel shines with the brand name PC makers like HP, Dell, Lenovo, and Acer but AMD excels in the gaming market, and many gamers like to build their own PCs.
If you look at the top selling CPUs on Amazon, it’s all AMD. AMD’s strength comes from its Ryzen X3D processors, which use additional cache specifically designed to improve performance in gaming workloads.
Nova Lake will be Intel’s next major desktop CPU generation targeting the gaming market so dominated by the Ryzen X3D line. Nova Lake will be manufactured on Intel’s 18A manufacturing process. Intel CEO Lip-Bu Tan said 18A is progressing ahead of schedule and that the company expects twice as many design wins at launch as it achieved with Panther Lake.
Intel has indicated that it will provide more information about Nova Lake at CES in Las Vegas in January 2027.
Not much is known about Nova Lake but there is plenty of rumors. The line will consist of a mix of Performance and Efficiency core and chips will come with as many as 52 cores.
Another rumored feature is Big Last Level Cache (bLLC), Intel’s answer to AMD’s 3D caching that made it so competitive. bLLC puts a larger pool of cache close to the processor cores than previously used.
During its earnings discussion, Intel warned that a sustained recovery in the PC market would depend on improved memory availability and more normalized pricing. The company expects the total addressable market for PC units to decline by approximately 10% in 2027.
Planning gamers to turn around its fortunes has its risk. The PC industry has been hit with a significant product shortage, of memory, storage, and GPUs. What is available is prohibitively expensive and many gamers are simply holding off purchases or upgrades rather than pay $500.00 for memory that used to cost $100 six months ago. Some NVIDIA GPUs are going for as much as $5,000.
Intel is not going to get very far if its CPUs are plentiful but memory, storage, and GPUs are not. But with data center construction exploding, the entire product supply is being sucked up for server technology, leaving gamers left holding the bag. If PC sales slump, Intel is out of luck.
Former Intel CEO Pat Gelsinger is backing a startup developing a high-bandwidth memory architecture designed to combine the speed of SRAM with the density of DRAM. According to The Register, Gelsinger is backing the effort through Playground Global, the venture capital firm where he became a partner in 2025 following his ouster from Intel.
Nagare Labs was founded by Georgia Institute of Technology researchers, and is developing a new memory technology called Z2RAM architecture designed to address one of the biggest constraints facing artificial intelligence infrastructure: the growing gap between processor performance and memory speed.
The technology targets the so-called memory wall, a growing problem in AI systems in which processors can perform calculations faster than conventional memory architectures can supply the required data. The result is a bottleneck where the CPU and GPU are left waiting, for lack of a better word, for the memory to catch up.
A workaround came in the form of high bandwidth memory (HBM), first developed by AMD in 2008, which put the memory on the CPU/GPU die right next to the processor rather than on DIMM sticks on the motherboard. This improved performance but not enough to satisfy data hungry CPUs and GPUs.
That’s where Nagare comes in. Founded by two professors at Georgia Tech whose research has focused on emerging memory technologies and semiconductor devices. The company’s approach uses oxide-semiconductor transistors rather than the capacitors found in conventional DRAM cells.
What they do is essentially increase the density of SRAM, allowing more memory to be packed into the CPU. SRAM is typically used in CPU and GPU caches and is several times faster than DRAM. But it has also much lower capacity, a few megabytes as opposed to gigabytes for DRAM.
A typical DRAM cell stores data using a transistor and a capacitor. Reading the stored charge is destructive, requiring the cell to be refreshed with the data after a read operation. Z2RAM instead uses two transistors, with the gate capacitance of one transistor serving as the charge-storage mechanism. This allows the stored information to be read without draining the charge, potentially reducing latency.
The architecture is also designed to stack memory layers directly above computing logic. Rather than relying on conventional memory stacks connected to processors through an interposer, Nagare aims to integrate memory and logic through a vertically layered structure using oxide-semiconductor processing.
This approach could reduce the distance data must travel between memory and compute, improving bandwidth while lowering the energy required for data movement.
Nagare’s initial design targets memory bit density five times greater than SRAM in a comparable area. That could allow a 64MB SRAM footprint to accommodate approximately 320MB of Z2RAM, according to the company’s technology concept.
Such capacity could be particularly valuable for AI inference, where accelerators must repeatedly access model weights and key-value (KV) caches used to retain information during text generation.
For accelerator designers, the benefits could include fewer memory bottlenecks, lower data-movement energy and improved utilization of processing resources. Larger on-chip memory capacity could also reduce the need to distribute workloads across as many individual accelerators in some applications.
The technology’s proposed vertical scaling is central to its manufacturing strategy. Nagare says its process is intended to build successive memory layers in a manner more closely resembling the vertical fabrication of NAND flash than the assembly of conventional high-bandwidth memory stacks.
If the approach proves practical at scale, it could offer a different route to increasing memory capacity without depending exclusively on smaller transistor geometries or increasingly complex packaging.
IBM and Intel are working together to add hardware-backed protection to sensitive AI workloads while they run.
The collaboration combines Intel Trust Domain Extensions (TDX) in Xeon Scalable 6 processors with IBM Sovereign Core’s operational controls and governance capabilities. The goal is to help organizations reduce the exposure of privileged data access during processing and retain authority over their AI environments.
The point is safeguarding sensitive information while it is being used, alongside controls governing who can access AI services and how those services operate. IBM said the approach is intended to support organizations handling confidential enterprise data and proprietary AI assets.
“As organizations bring increasingly sensitive AI workloads, data and intellectual property into sovereign environments, they need more than governance and policy controls. They need confidence that those protections extend all the way through processing,” Anand Pashupathy, vice president and general manager of Intel Product Assurance and Security said in a statement.
IBM Sovereign Core provides a customer-operated control plane, identity and access management within a defined sovereign boundary, governed AI services and automated compliance controls. It also continuously keeps logs of activity to show it is working as designed.
Intel TDX adds hardware-backed isolation for selected workloads. Its attestation capabilities can provide information about the execution environment, complementing Sovereign Core’s compliance monitoring and evidence collection.
The combination of the two technologies breaks down into three separate categories: maintaining operational authority over the AI environment, protecting supported workloads during execution and producing evidence about the protections in place. IBM said these capabilities are complementary rather than interchangeable guarantees.
IBM highlighted financial institutions, government agencies, and other highly regulated organizations as potential users. These organizations have to determine which AI models are approved, where inference runs, who can access services and how operations are monitored before deploying workloads involving confidential information.
IBM says Sovereign Core’s modular architecture allows organizations to choose infrastructure, applications, models, and services within their sovereign environments. The combined approach is not intended to prescribe a particular AI stack. Customers can use IBM, third-party, or open-source components and apply additional workload protections according to their requirements.
IBM warned that confidential computing does not replace broader security architecture, access management or compliance processes and attestation alone does not establish regulatory compliance. Organizations must assess where hardware-backed isolation fits their workload sensitivity, threat models and operational needs.
Pricing and general availability were not disclosed.
Breakthroughs Quantum Can Deliver, the TAM Each One Opens, and Use Cases AMD, AWS, Google, IBM, IonQ, Microsoft, and NVIDIA Are Targeting
What You Need to Know
AI Has Conquered Knowledge Work and Stalled at the Boundary of Physics: Generative AI learns from recorded human output and knowledge work is almost entirely recorded while science is not. The behavior of electrons in a catalyst or an enzyme cannot be learned from data that does not exist and cannot be computed classically at scale. That is the barrier AI has run into in science, and the barrier quantum computing is built to cross.
The Quantum TAM Will Reach $1.51 Trillion a Year by 2040: About $650 billion a year will come from productivity gains in the parts of existing industries that depend on computation. About $860 billion will come from new product markets that do not exist until a scientific barrier falls. Those include catalysts that replace Haber-Bosch, solid state battery materials, drugs against undruggable targets, materials that AI can propose but cannot validate, and healthcare decisions that depend on biology, classical models cannot simulate.
The Market Has Underestimated Quantum’s Impact: Prevailing expectations size quantum as a niche accelerator worth tens of billions in vendor revenue. The $860 billion new market layer in this forecast consists of products that will exist only because quantum made the underlying discovery. The same mistake was made with AI in 2012, when the technology was priced as a better image classifier rather than as a restructuring of knowledge work. Futurum’s view is that quantum is being priced today as a better simulator rather than as a restructuring of the physical economy.
Seven Vendors Have Already Declared Their Use Cases: AMD, AWS, Google, IBM, IonQ, Microsoft, and NVIDIA have each named the problems they will attack first. The list covers catalysis, battery and materials discovery, drug targets, healthcare, and optimization. The first breakthroughs will land between 2029 and 2033 and the products they enable will reach the market between 2033 and 2040.
2029 Will Be Quantum’s ChatGPT Moment, but QPU Output Will Not Ramp Like AI Chips: The first validated quantum chemistry result on an industrial molecule is expected alongside the first systems with a few hundred logical qubits in 2029. Demand will inflect the way AI demand did in late 2022. Adoption will be slower because AI accelerators rode an existing 300mm foundry and memory supply chain while QPUs depend on wafer lines, cryogenics, and lasers that are only now being industrialized at Anderon, SkyWater, and GlobalFoundries.
AI and Quantum Are Both/And, Not Either/Or: AI proposes candidates, and quantum validates them. GPUs decode quantum error correction in real time, and quantum results become the training data AI in science has lacked. Every full-stack vendor is building hybrid systems rather than choosing a side.
The Futurum View
Futurum’s view is that quantum computing in 2026 sits where AI sat in 2012 and that the next 15 years will rhyme. AI did not disrupt knowledge work in a single step. Deep learning proved itself in image recognition in 2012. The transformer arrived in 2017 and made scale the strategy. ChatGPT turned a research capability into an enterprise habit in late 2022. By 2026, agentic systems will write code, draft contracts, and run analyses as routine. The cumulative effect redrew the economics of every profession that works with words, numbers, and images.
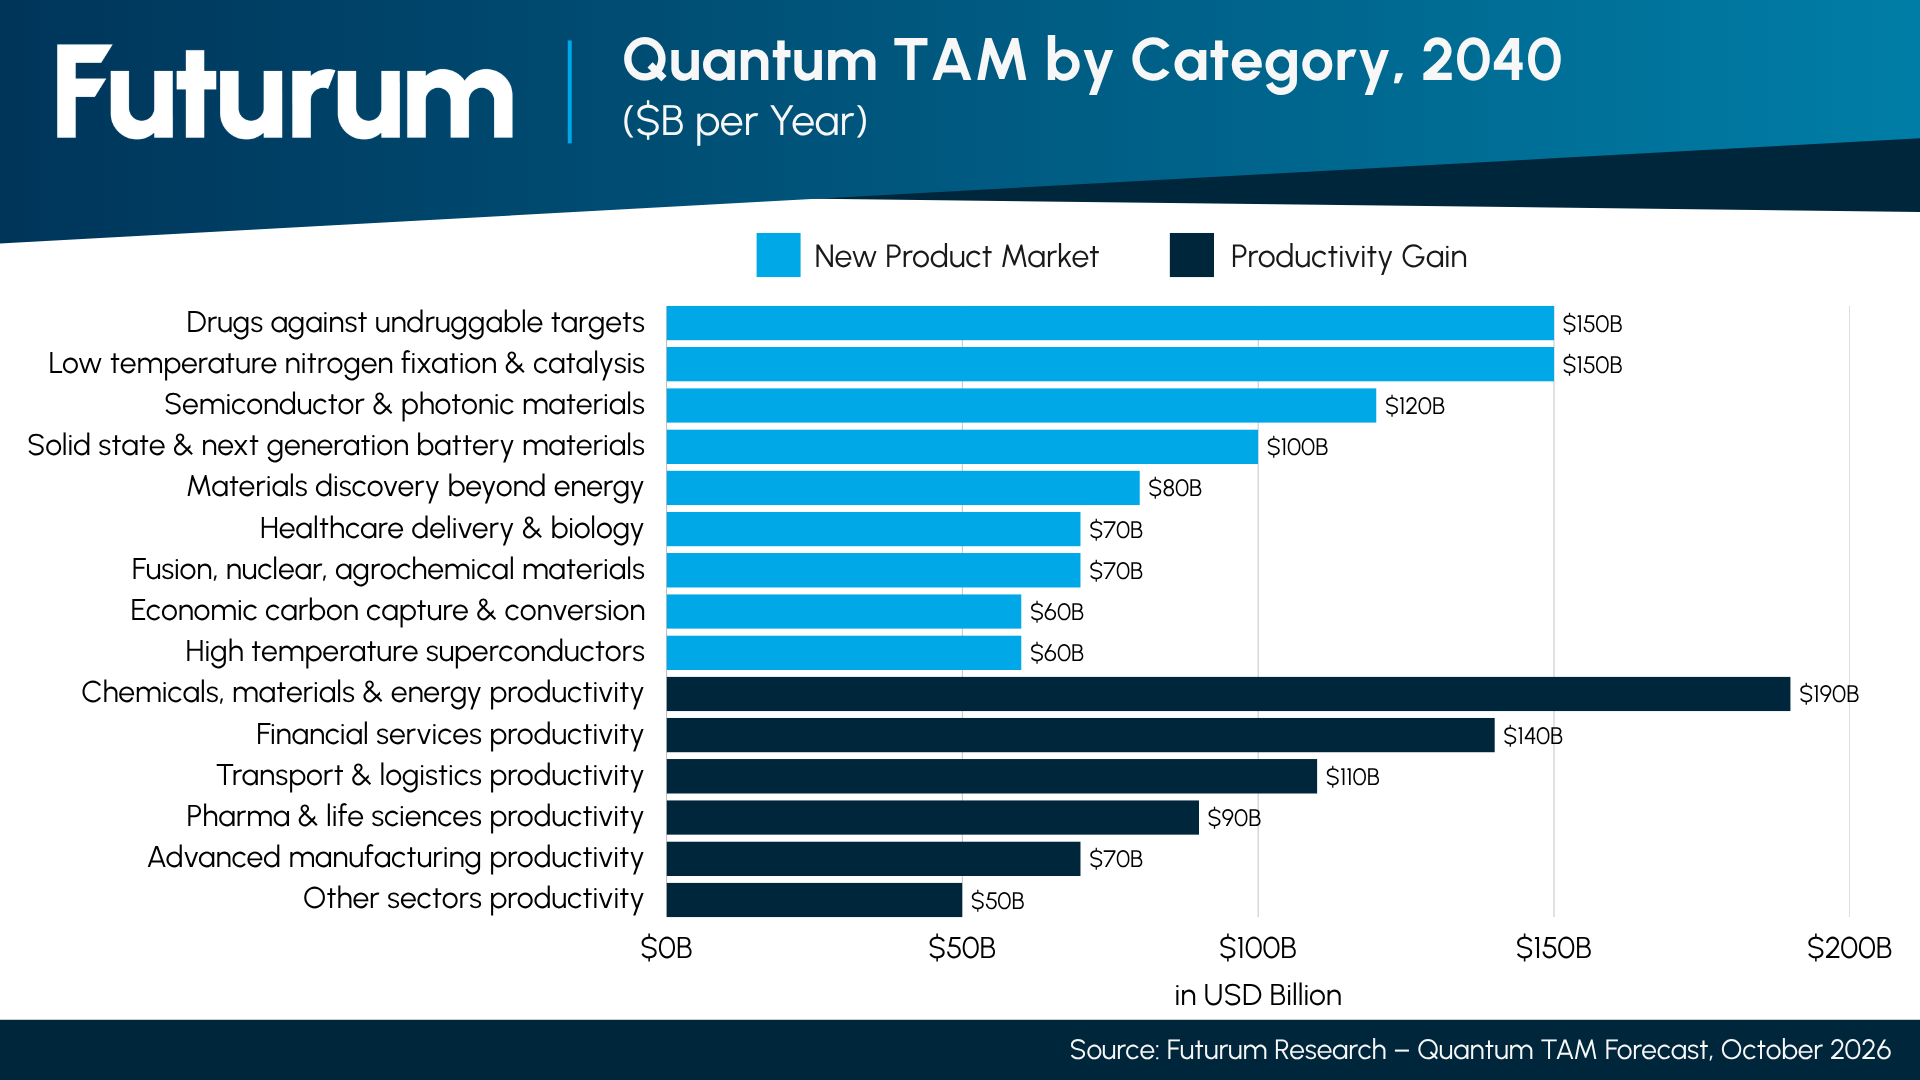
Quantum has just produced its equivalent of the “AI 2012 moment” on several fronts at once. Google’s Willow showed that adding qubits reduces logical error rather than adding noise. Quantinuum’s Helios shipped with 48 error-corrected logical qubits. Google’s Quantum Echoes ran a verifiable physics calculation roughly 13,000 times faster than the Frontier supercomputer. IBM moved quantum advantage from roadmap to demonstration, and Microsoft produced a second-generation topological device. Enterprises outspent governments on quantum for the first time, and the United States funded a merchant quantum wafer foundry. None of these alone is the breakthrough. Together, they are the pattern that preceded AI’s takeoff. The physics question has been answered. What remains is engineering, manufacturing, and adoption. AI reorganized the third of economic activity that is recorded information work. Quantum will reorganize the third, which depends on the physics of materials, molecules, and complex systems. Figure 1 sets out where that addressable market will sit in 2040.
Figure 1: Quantum TAM by Category, 2040 ($B per Year)
Source: Futurum Research – Quantum TAM Forecast, October 2026
Where AI Stops at the Science Barrier
AI’s impact has concentrated in knowledge work because language, code, images, and transactions are abundantly recorded, so models can learn the mapping from input to output without understanding the mechanism. Science works in the opposite direction. The governing equations of chemistry and materials are known. They cannot be solved exactly once more than a few dozen electrons interact, because the number of states to track doubles with each additional particle. Classical computers approximate instead. Machine-learned surrogates inherit the error of those approximations, which is often large enough to misjudge whether a reaction will proceed. GPU acceleration has made the approximation faster, not more accurate.
The results show where AI in science has and has not delivered. It has delivered where the task is pattern recognition over existing data, as in protein structure prediction. It has stalled where the task is the physics of strongly interacting electrons, as in catalysis, battery interfaces, and enzyme-active sites. Those are the problems whose solutions open new markets and that quantum computers simulate natively. AI is the front end that proposes and screens and quantum is the back end that can compute what AI cannot learn.
The Breakthroughs and the Markets They Open
The forecast starts from world output. Global output is roughly $115 trillion in 2026, and Futurum carries it to roughly $175 trillion in 2040 on a 3% nominal growth path. Six sector groups where quantum’s problem classes recur make up about $35 trillion of the 2026 total. Chemicals, materials, and energy and financial services contribute about $10 trillion each, transport and logistics about $7 trillion, advanced manufacturing about $6 trillion, pharma about $1.8 trillion, and insurance, telecom, and public services the rest. Within each group, Futurum isolates the share of output that depends on computation in research, engineering, risk analytics, and network planning. Those shares run from 12% in advanced manufacturing to 40% in pharma and sum to about $6.8 trillion. A 10% productivity uplift on that pool, calibrated to the level effect of the 1995 to 2005 information technology wave and phased over 12 years from 2030, yields the $650 billion productivity layer. Information and communications technology enters through telecom in that group and through the semiconductor row in Table 1. Cryptography is excluded on purpose because breaking encryption is a threat rather than a market, and post-quantum migration is a classical upgrade that will proceed regardless. Media has no computation-dependent pool large enough to separate.
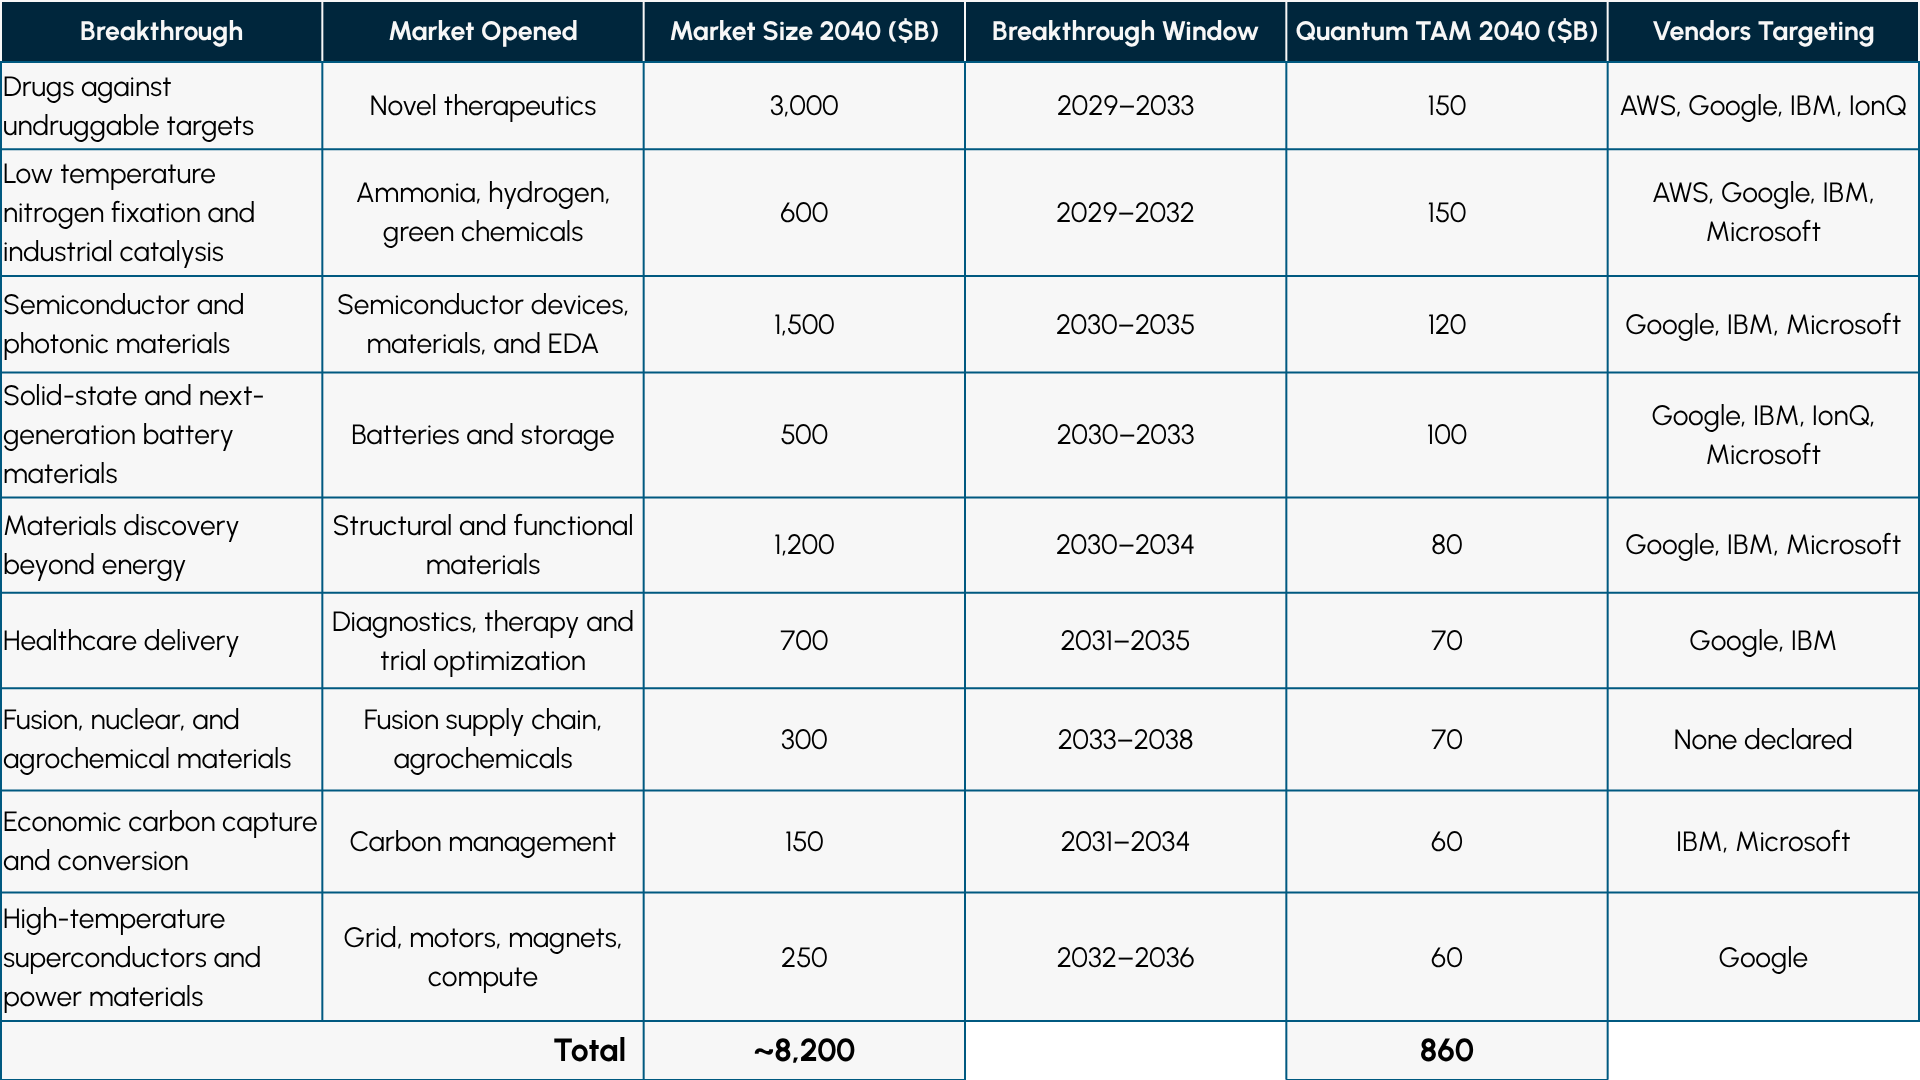
The new market layer is built differently. Table 1 lists the barriers Futurum judges most likely to fall to quantum computation between 2029 and 2038, the market each opens, and the 2040 size of that market, drawn from sector forecasts. The quantum TAM is the share of each market’s 2040 size that depends on a design or discovery classical methods cannot produce, phased for the five- to eight-year lag between a validated breakthrough and a shipping product. The $8.2 trillion in the market size column is the collective size of the markets quantum will reach into, and the $860 billion in the quantum TAM column is the part that will exist only because quantum made the underlying discovery.
Table 1: Breakthroughs Quantum Can Deliver by Total Addressable Market
Source: Futurum Research – Quantum TAM Forecast, October 2026. Market sizes are 2040 sector forecasts. Quantum TAM and windows are Futurum assumptions. Rows are sorted by quantum TAM.
Four of these lead the field. Haber-Bosch consumes 1% to 2% of global energy because no one has resolved the enzyme that fixes nitrogen at ambient conditions. A few percent of a $3 trillion pharmaceutical market is larger than the entire simulation budget that quantum will displace. Semiconductors are the largest industrial base in the table because dopant and defect physics, 2D channels, memory cell chemistries, and photonic materials all sit in the regime that classical process simulation approximates. Every automaker and cell maker already pays for battery simulation that cannot reach the accuracy the interface chemistry demands. Materials discovery and healthcare widen the aperture. Quantum will validate the millions of candidates that generative AI now proposes and will shift healthcare from molecules to care decisions. Both will mature later than catalysis because they depend on data and regulatory pathways as well as on qubits.
Productivity Gains Come First and New Markets Compound Longer
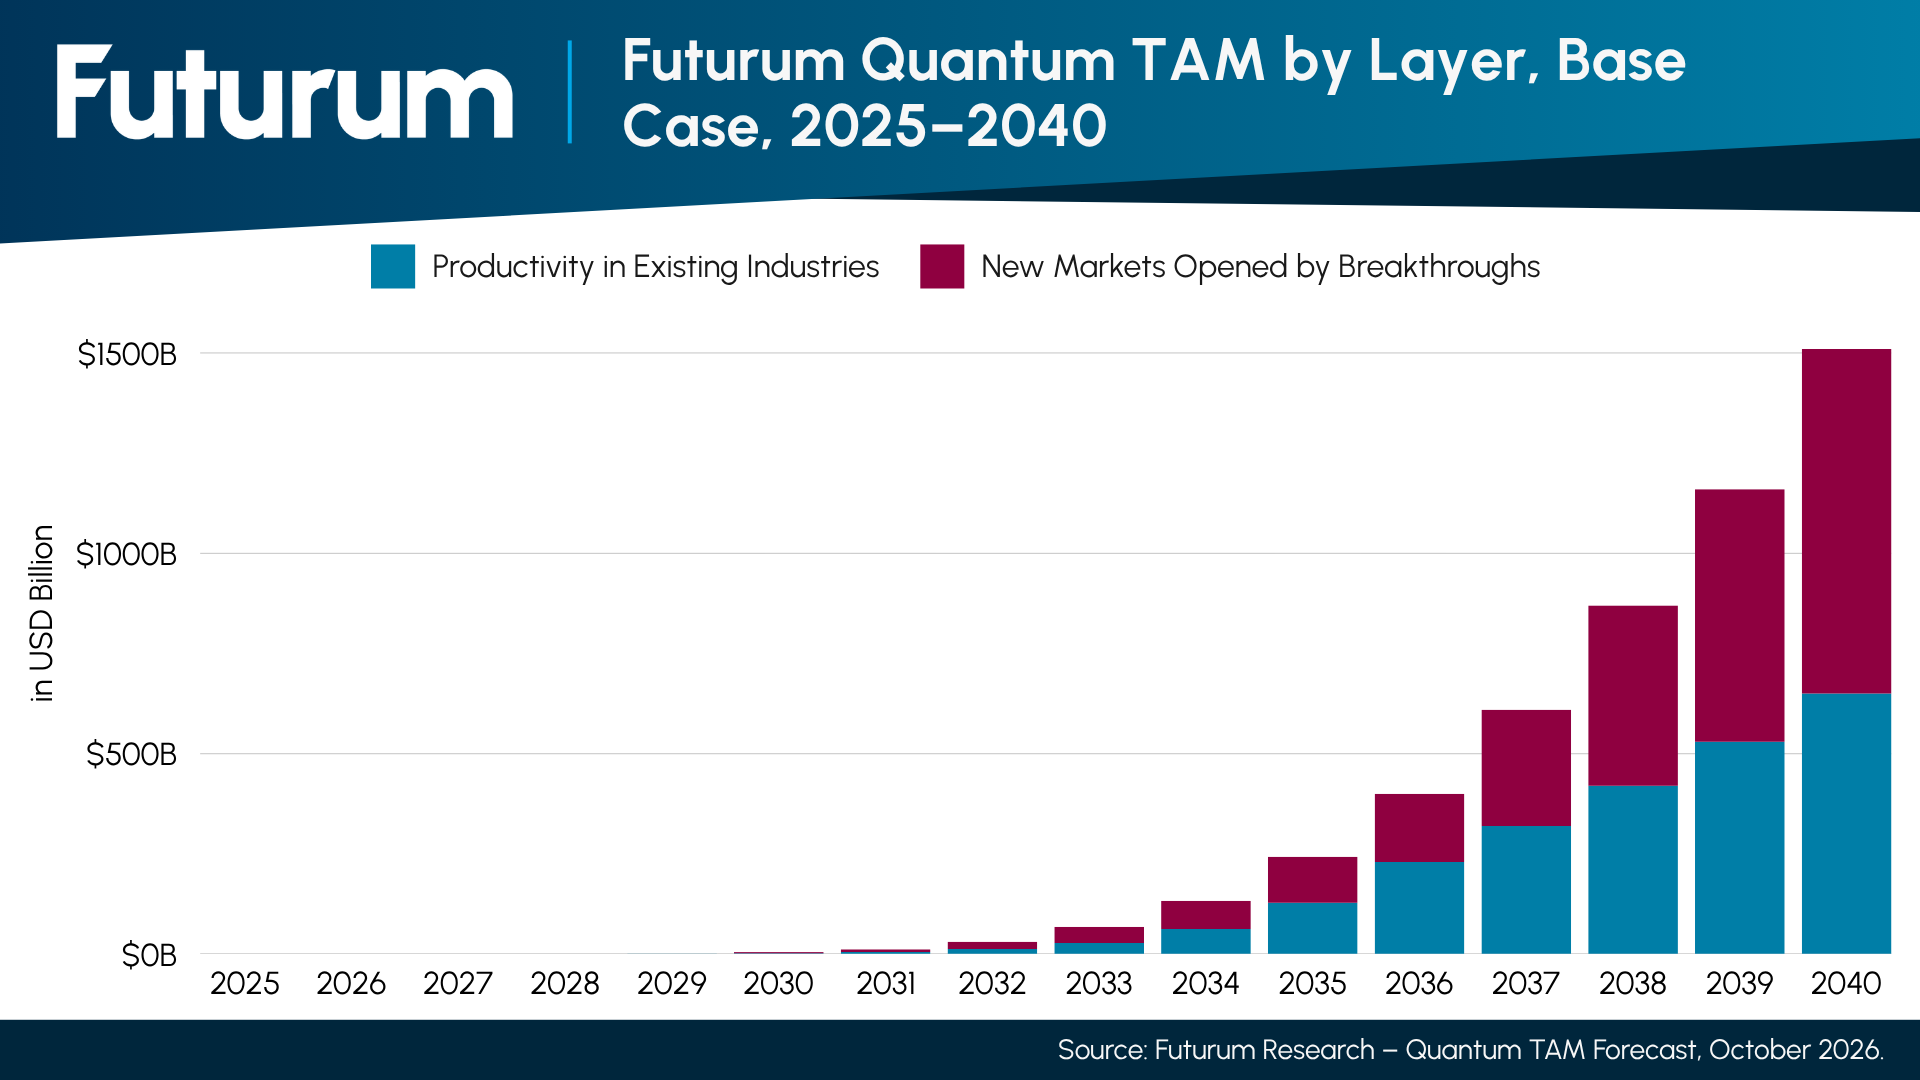
Figure 2 sets out both layers by year. The productivity layer starts in 2030 and reaches $650 billion in 2040. The new market layer lags it by two to three years because a validated breakthrough must become a patent, a pilot plant, or a clinical candidate before it becomes a market. It will still be accelerating in 2040.
Figure 2: Futurum Quantum TAM by Layer, Base Case, 2025–2040
Source: Futurum Research – Quantum TAM Forecast, October 2026. Values are the annual addressable market in each layer. If error correction arrives around 2027 to 2028, the 2040 total will reach about $2.1 trillion. If it slips to 2033, the total will reach about $620 billion.
2029 Will Be the ChatGPT Moment and the Ramp Will Be Supply Constrained
Through 2029, the addressable market will be close to zero, though many pilots are already active. Futurum expects 2029 to be Quantum’s ChatGPT moment. It is the year the first systems with a few hundred logical qubits ship against vendor roadmaps, and a quantum chemistry result on an industrial molecule is validated beyond classical reach. Demand will inflect the way AI demand did in late 2022. Supply will not. AI accelerators scaled at roughly 78% a year because they rode an existing 300mm foundry, memory, and packaging supply chain. QPUs have no such inheritance. Qubit wafers, cryogenic readout chains, dilution refrigerators, and ultra-stable lasers are all produced at research volumes today.
That constraint is why the industry is building a quantum foundry layer now. IBM’s Anderon is a standalone 300mm quantum wafer foundry in Albany that finalized a $1 billion CHIPS Act award in September 2026, matched by $1 billion from IBM. The same program put $375 million into GlobalFoundries and roughly $100 million each into six hardware companies, with the government taking equity in each. IonQ bought SkyWater outright. Anderon and SkyWater are the first merchant 300mm lines open to QPU vendors in general, and their yield ramp, rather than enterprise demand, will set how fast the market in Figure 2 opens from 2030 to 2035.
What the Vendors Plan to Attack and the TAM Each Use Case Unlocks
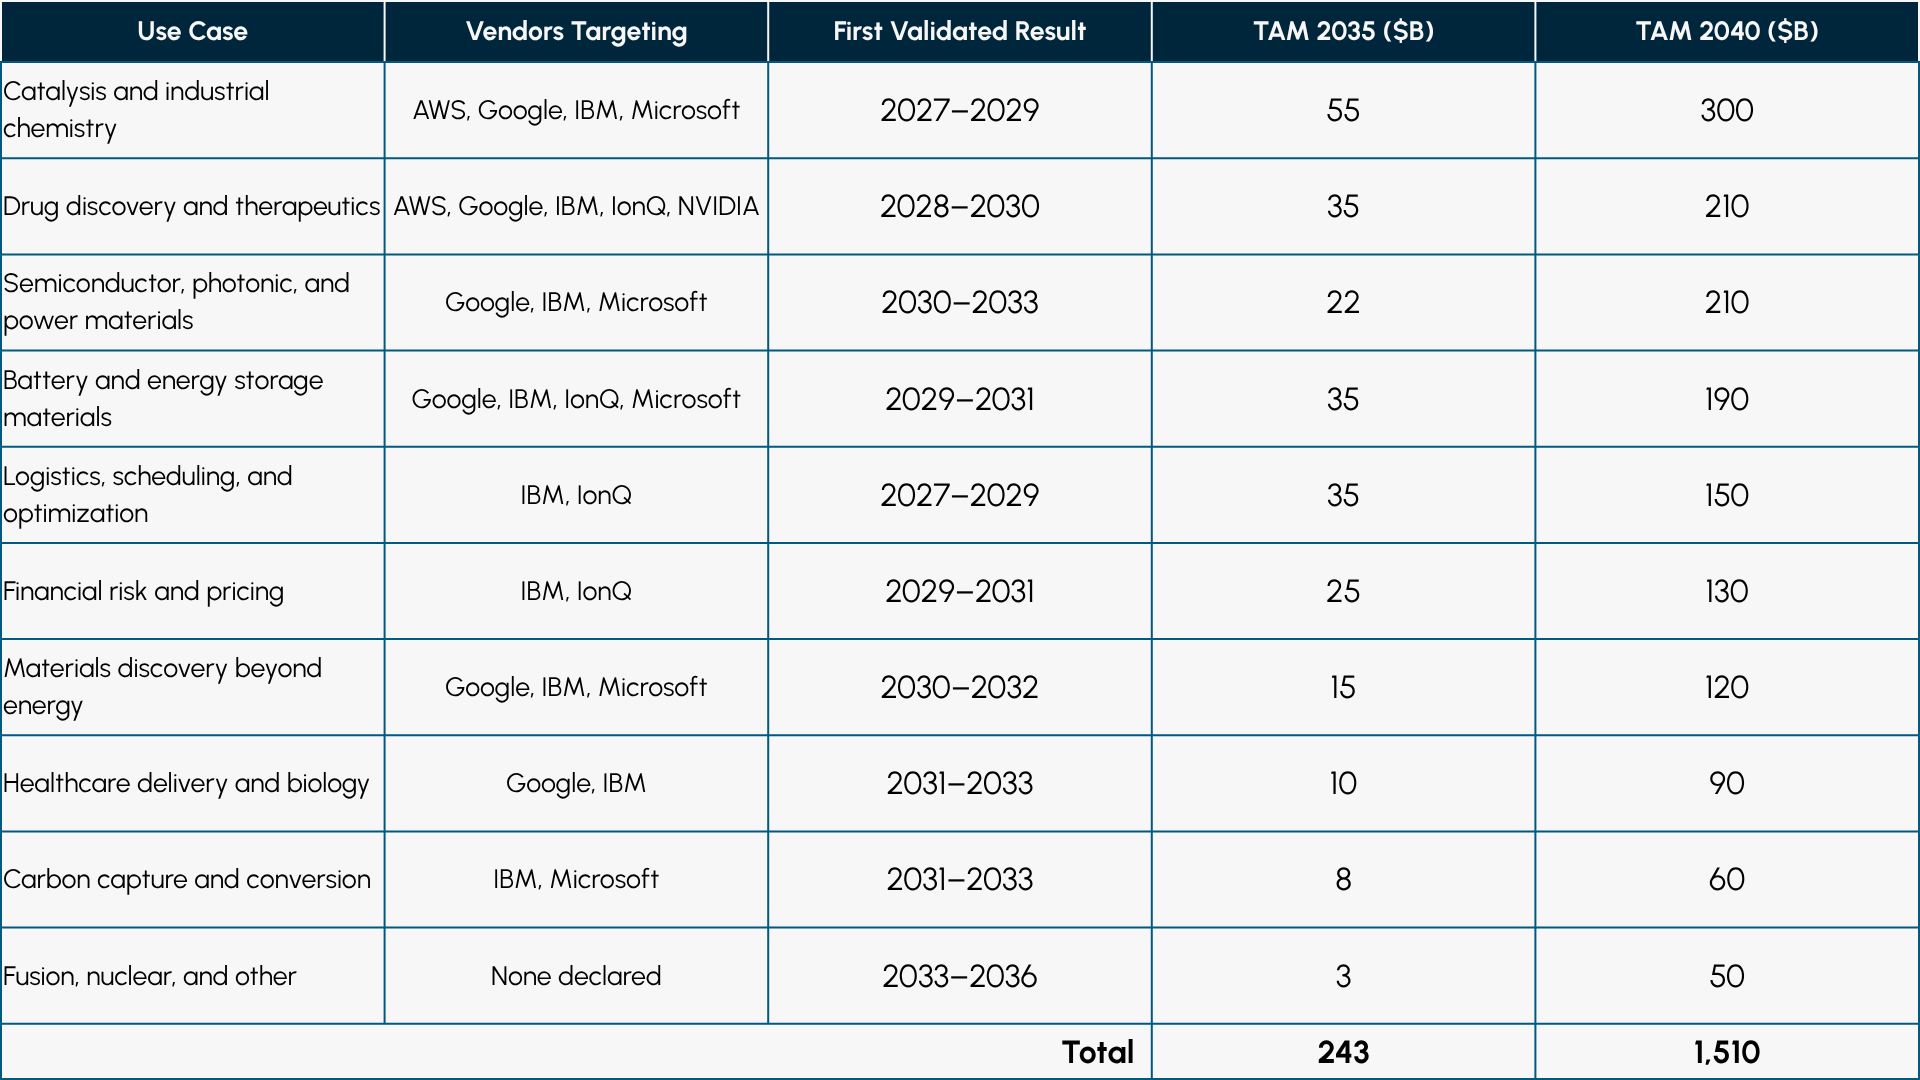
Seven vendors have each named their first targets, and there is high overlap. IBM has committed to demonstrating quantum advantage in 2026, starting with chemistry and then optimization, with Starling’s 200 logical qubits in 2029 aimed at materials and drug development alongside Boeing and the Cleveland Clinic. Google has set a five-year horizon for materials, medicine, and energy applications possible only on quantum computers. IonQ is attacking drug discovery with AstraZeneca, battery chemistry with Hyundai, and logistics with Einride. AWS has said chemistry and materials simulation is where quantum will shine first and is building Ocelot to cut the cost of error correction. Microsoft is pairing Majorana with an agentic discovery platform already used by BHP, Syensqo, and Ginkgo Bioworks. NVIDIA and AMD are positioning themselves as the classical host for all of the above. Table 2 maps those declared use cases to the TAM each one unlocks and to the year each will first produce validated results.
Table 2: Declared Vendor Use Cases, and the Quantum TAM Each Unlocks
Source: Futurum Research – Quantum TAM Forecast, October 2026.
Catalysis, batteries, and therapeutics will account for roughly half of the TAM in both 2035 and 2040, and they are the three every full-stack vendor is targeting. Optimization and finance will open earliest but plateau soonest because classical heuristics and AI will keep narrowing the gap there, while materials discovery and healthcare will start later and compound longer.
What to Watch:
The First Industrial Chemistry Result: A quantum calculation of a catalyst or enzyme active site validated against experiment and beyond the reach of the best classical method will move quantum from research budgets to product budgets. IBM’s 2026 advantage demonstrations and Google’s verifiable algorithms are the first candidates.
Discovery Contracts, Not Compute Contracts: The new market layer will show up first as milestone and royalty agreements between quantum vendors and pharma, chemical, and battery companies. The first such deal with disclosed economics will mark its start.
Quantum Wafer Yield at Anderon, SkyWater, and GlobalFoundries: Value realization after 2029 will be gated by QPU output rather than demand. Yield on schedule will support the base case, and a stall will push toward the delayed case regardless of error-correction progress.
Hybrid Workflows That Close the Loop: The first disclosed pipeline in which AI-proposed candidates are validated on a QPU and fed back to retrain the model will confirm that the two technologies compound. If AI surrogates keep closing the accuracy gap alone, the new market layer will shrink.
Delivery Against 2029 Roadmaps: IBM Starling, Microsoft’s 2029 target, AWS’s five- to seven-year window, and IonQ’s 2030 roadmap cluster on the same inflection. Slippage of more than a year on two of them would move the inflection to 2032 or later and cut the 2035 TAM by roughly two-thirds.
Disclosure: Futurum is a research and advisory firm that engages or has engaged in research, analysis, and advisory services with many technology companies, including those mentioned in this article. The author does not hold any equity positions with any company mentioned in this article.
Analysis and opinions expressed herein are specific to the analyst individually and data and other information that might have been provided for validation, not those of Futurum as a whole.
Intel Corp. shares tumbled roughly 20% in extended trading Thursday after the semiconductor giant issued a fourth-quarter revenue outlook that fell sharply below Wall Street estimates, weighed down by an operational disaster in Israel and a prolonged slump in personal computer demand.
The company forecast fourth-quarter revenue between $15 billion and $16 billion, significantly trailing analysts’ average projection of $17.07 billion, according to data compiled by LSEG. Adjusted earnings are expected to land at 25 cents per share, falling well short of the 43 cents anticipated by analysts. The gloomy outlook overshadowed an otherwise solid third quarter, in which revenue rose 21% year-over-year to $16.5 billion.
Compounding the company’s challenges, Intel disclosed that an October explosion at its Kiryat Gat fabrication facility in Israel will erase roughly $600 million in revenue across two quarters.
The blast, which killed two workers, injured another, and idled the plant for approximately two weeks, is expected to reduce fourth-quarter revenue by about $300 million and compress gross margins by roughly 200 basis points. A similar financial drag is projected for the first quarter of next year.
Intel Chief Financial Officer David Zinsner told Reuters that engineers are assessing wafers to determine which units remain salvageable. The Kiryat Gat site primarily manufactures server and data center chips utilizing Intel’s 10-nanometer process. While production is slated to begin ramping back up by the end of this week, Zinsner acknowledged that the operational fallout could widen depending on final inspection results.
The factory outage hits as Intel struggles to navigate persistent production bottlenecks and satisfy soaring demand for its artificial intelligence (AI) hardware. CEO Lip-Bu Tan emphasized that the company’s immediate priority remains unlocking supply to satisfy robust orders for its flagship Xeon server processors.
Simultaneously, a persistent downturn in the consumer market continues to erode the company’s core business. PC chip sales fell 5% in the third quarter to $8.1 billion, missing expectations of $8.98 billion. Zinsner warned that fourth-quarter PC revenue could drop in the mid-twenty percentage range as rising memory costs inflate retail PC prices.
“Looking ahead, we see the PC slowdown continuing at least through the first half of next year,” Zinsner said, noting that Intel will maintain disciplined capital spending to expand manufacturing capacity over the long term.
The report marks a sudden reversal for a stock that had more than doubled this year. Intel warned it expects to burn cash in 2026 amid aggressive capital expenditures tied to its multi-billion-dollar foundry turnaround, designed to challenge contract manufacturing leaders such as TSMC. That ambitious push was bolstered in August by a $23 billion upsized equity offering.
Trading below $76 per share after hours, the stock touched its lowest point since April as investors recalibrate expectations against steepening manufacturing costs and lingering market headwinds.
Semiconductor developer Marvell Technology is in advanced negotiations to acquire optical technology provider Lumentum Holdings, a deal that would expand the chipmaker’s AI networking business by adding laser manufacturing and optical communications technology.
The companies could announce an agreement as early as next week, according to Bloomberg News, which cited people familiar with the discussions. Lumentum has a market value of approximately $83 billion, making the potential acquisition one of the tech industry’s largest.
Neither company has confirmed the negotiations, and the purchase price remains undisclosed. A transaction could involve stock, though the terms remain uncertain and negotiations could still fail.
The proposed acquisition comes as Marvell expands its AI business. The company recently raised its fiscal 2028 revenue forecast from $15 billion to $20 billion, indicating strong demand for its custom AI processors and networking chips. Marvell’s shares have nearly tripled in 2026, providing the company with a stronger position to finance acquisitions through stock.
But investors appear concerned about the potential costs. Following reports of the negotiations on October 28, Marvell shares declined 8.44% in after-hours trading, while Lumentum gained 8.64%.
Marvell’s potential acquisition highlights that networking capacity and component supply offer as much competitive edge as the chips themselves. The deal could also raise questions among competing chipmakers and optical equipment customers about continued access to Lumentum products.
High Demand for Optical Technology
Lumentum develops lasers, optical transceivers and related components that transmit data using light rather than electrical signals. These technologies are becoming crucial as data centers deploy larger clusters of GPUs for AI training and inference. Lumentum could provide Marvell with additional technology needed to transfer massive volumes of data between processors while reducing network bottlenecks.
Lumentum’s manufacturing capacity has been under pressure. Lumentum CEO Michael Hurlston recently said that its optical components are sold out through early 2029. For certain products, the company expects to leave approximately 70% of customer demand unmet next year.
To expand production, Lumentum plans to invest at least $350 million in manufacturing facilities in Japan, including those producing indium phosphide components used in optical communications. The strong demand has supported remarkable revenue growth. Lumentum reported fiscal fourth-quarter 2026 revenue of $1.006 billion, up 109.3%, while annual revenue climbed 83.2% to $3.01 billion.
Expanding AI Networking Portfolio
Marvell already purchases lasers from Lumentum, so an acquisition would bring an existing supplier into its business while broadening its optical technology capabilities.
The proposed purchase would build on Marvell’s $3.25 billion acquisition of Celestial AI, announced in December 2025 and completed in February 2026. That transaction, which could reach $5.5 billion if performance milestones are achieved, gives Marvell access to photonic interconnect technology geared for high-speed communications between processors.
Combining Celestial AI’s technology with Lumentum’s optical components could allow Marvell to supply more of the hardware required for AI networking, including custom silicon, photonic connections and laser technology. Marvell also works with Microsoft, Amazon Web Services and Google on custom silicon and related infrastructure.
Bernstein analysts have warned that financing a transaction of this size could pose challenges, particularly as Marvell integrates Celestial AI. Marvell reported approximately $3.92 billion in cash and equivalents at its latest quarter-end, far below Lumentum’s market valuation.
Another consideration is NVIDIA’s investment in Lumentum. In March, NVIDIA invested $2 billion through convertible preferred shares as part of an optical technology partnership.
Hyperscaler earnings week has become an infrastructure spending competition. We compare capital budgets, count accelerators and discuss gigawatts as though the biggest number settles who is winning. Microsoft and Alphabet together reported $90.7 billion in cash additions to property and equipment for the quarter ended September 30. Those are company-wide investments, not exclusively AI spending, but they illustrate the scale of the commitment. What they cannot tell us is how much productive computing capacity those dollars will deliver. That requires looking inside the systems being built, where expensive processors can spend valuable time waiting for something else to happen.
My colleague Brendan Burke at Futurum recently put networking at the center of that discussion after speaking with Gilad Shainer, NVIDIA’s senior vice president of networking. Brendan’s argument deserves attention because the debate over GPUs and custom accelerators often treats the connections between them as a supporting detail. At large scale, those connections help determine whether the investment works. A processor can be extraordinarily fast on its own and still contribute to a system that performs well below expectations. Buying another rack does not automatically fix the reason the existing racks are waiting.
Consider what a distributed AI workload requires. Accelerators exchange information within a rack, across racks and sometimes between facilities, while also accessing storage and serving applications. During synchronized training, one delayed transfer can hold up work involving many processors. Congestion, uneven traffic distribution and recovery from failed links therefore become economic issues, not merely network administration problems. Maximum bandwidth tells us something about a connection’s potential. Buyers also need to know how predictably the system moves data when it is busy and what happens when a component fails.
The Cost of Waiting
Meta’s account of training Llama 3 provides a useful reality check. During a 54-day period, it recorded 419 unexpected interruptions, yet maintained more than 90% effective training time. Network switches and cables accounted for 8.4% of those interruptions; GPU-related problems were the largest category. The impressive accomplishment was keeping training productive through automation, diagnosis and recovery despite the failures. This was an operating challenge across the system, and it would be wrong to suggest a better network alone could have solved every problem. It would be equally wrong to judge the installation solely by how many GPUs it contained.
CoreWeave offers another way to see the difference between installed hardware and delivered performance. In its published DeepSeek-V3 MLPerf training benchmark, 2,048 GPUs completed the task in 5.54 minutes, while 8,192 GPUs finished in 2.02 minutes. Four times the hardware delivered approximately 2.74 times the speed. These were defined benchmark runs, not the original model’s entire training process compressed into minutes, and CoreWeave says they ran on customer-serving production infrastructure. The results demonstrate substantial scaling, while also showing that adding hardware does not yield a proportional reduction in completion time. They do not isolate networking as the cause of the gap.
There can still be excellent reasons to pay for that faster result. A research team may value completing an experiment sooner, and a service provider may need additional capacity to meet demand. But faster completion and lower cost are different outcomes, and buyers should know which one they are purchasing. Procurement comparisons that stop at accelerator prices miss the engineering required to turn those devices into a productive system. At these investment levels, the cost of waiting deserves as much scrutiny as the cost of buying.
NVIDIA is Selling the Integration
NVIDIA understands this relationship. Its offering reaches across accelerators, interconnects, switches, network adapters and the software that coordinates their work. The commercial value comes partly from engineering and validating those elements together, including their behavior under congestion and failure. For a customer, that can mean less integration work and a clearer path to diagnosing problems. I see that accumulated engineering experience as a more persuasive explanation of NVIDIA’s advantage than a checklist declaring that it covers five networks while someone else covers fewer.
The Spectrum-X research Brendan highlighted illustrates the point. NVIDIA reports a simulation in which training steps remained at 668 milliseconds with and without background traffic, while its conventional Ethernet baseline rose from 735 milliseconds to 1.18 seconds. That is meaningful evidence of isolation under the conditions tested. It is also vendor research against a specified Ethernet configuration, not a demonstration that every competing modern fabric suffers the same slowdown. The practical lesson is that a workload’s performance can depend heavily on what else shares the infrastructure. Predictability has value when customers are paying for service levels rather than laboratory peaks.
The optical discussion fits this broader systems view. Copper, pluggable optics and co-packaged optics address different combinations of distance, power, density and serviceability. NVIDIA’s participation with Cisco in developing USFP pluggables can coexist with its investment in co-packaged optics. USFP remains an announced development effort, and we should distinguish that from available products. Customers should evaluate the connection required for a particular job rather than interpret every form-factor announcement as a reversal of strategy. The economics depend on how the components work together in the intended deployment.
NVIDIA’s strategy becomes especially interesting when the accelerator belongs to somebody else. Through NVLink Fusion, companies can build custom silicon into infrastructure that uses NVIDIA interconnect technology and its broader ecosystem. d-Matrix plans to integrate its Raptor inference processors into NVIDIA MGX racks with NVLink, Spectrum-X and other NVIDIA components, with initial availability expected in the fourth quarter of 2027. That is a concrete commitment, although its production economics remain ahead of us. If it succeeds, a customer choosing a specialized accelerator could also become a larger customer for NVIDIA infrastructure.
AWS illustrates a more selective approach. Its planned Trainium4 integration with NVLink Fusion sits alongside AWS technologies including EFA networking and Nitro, with Trainium4 delivery expected to begin in 2027. Adopting NVIDIA at one layer does not require adopting it everywhere. These arrangements could become increasingly relevant as inference systems assign different stages of a request to different processors. Processing the prompt and generating the response place different demands on hardware, but specialization only pays when the cost of moving data between stages stays manageable. More accelerator choice can expand NVIDIA’s opportunity without guaranteeing it ownership of the whole system.
Make the System Prove Itself
There are credible alternatives to buying that integration from one supplier. Meta reported tuning its InfiniBand and Ethernet-based RoCE clusters to equivalent performance for its particular large-model workloads. OpenAI describes production networking built around its Multipath Reliable Connection protocol, developed with AMD, Broadcom, Intel, Microsoft and NVIDIA. These examples show what capable operators and their partners can accomplish. They also reveal the resources involved: the alternative to a deeply integrated platform may require substantial engineering of your own. Customers need to compare that work, its timetable and its operational risks alongside equipment prices.
For an enterprise buying cloud capacity, that scrutiny belongs in the service evaluation even if the provider owns the switches. Ask how long a training job takes, how much progress survives a failure and how inference behaves when neighboring workloads get busy. Compare costs at a specified response time and output quality, with power, support and engineering included where relevant. NVIDIA has a formidable position because it has spent years making these pieces work together, but its advantage should be demonstrated in the customer’s operating results. A purchase order records the accelerators acquired. The completed work reveals how much AI capacity the customer actually bought.
Oracle used AI World 2026 to sign compute deals across five silicon suppliers in one day, expanding NVIDIA Vera Rubin to multi-gigawatt scale while becoming the first hyperscaler outside Google to offer TPUs and adding Cerebras, SambaNova, and Intel Diamond Rapids capacity. Futurum assesses what a five-architecture OCI means for the design of AI Superclusters.
What Is Covered in This Article:
NVIDIA Vera Rubin NVL72 general availability on OCI and a planned multi-gigawatt expansion
Google TPU 8t and 8i on OCI in calendar 2027, the first hyperscale cloud outside Google to offer TPUs
Cerebras wafer-scale inference and SambaNova SN50 decode capacity coming to OCI
A multiyear Intel collaboration putting Diamond Rapids in planned OCI X14 shapes
Oracle Acceleron networking replacing some NVIDIA networking silicon in OCI systems
The News: Oracle announced compute agreements at AI World in Las Vegas on October 27, 2026 that place five external silicon architectures inside Oracle Cloud Infrastructure. NVIDIA Vera Rubin NVL72 racks and Vera CPUs reached general availability on OCI, and the two companies plan to expand OCI Superclusters to multi-gigawatt scale. Google’s eighth-generation TPUs, the 8t for training and the 8i for inference, will come to OCI in calendar 2027, the first TPU offering on a hyperscale cloud outside Google per Oracle. Cerebras plans to bring wafer-scale inference to OCI in calendar 2027, and SambaNova will deploy its fifth-generation SN50 Reconfigurable Dataflow Units for decode-stage inference. Intel and Oracle announced a multiyear Xeon collaboration, including planned OCI X14 offerings built on Diamond Rapids. Below the silicon, Oracle’s Acceleron networking will link TPU clusters, NVIDIA systems, and the rest of the OCI data center.
“Bringing Google TPUs to OCI gives customers access to multiple leading AI compute architectures in one cloud,” said Mahesh Thiagarajan, President of Oracle Cloud Infrastructure. The companies disclosed no deal values.
Oracle Makes the Supercluster Multi-Silicon at AI World 2026
Analyst Take: Oracle has turned OCI into the first hyperscale cloud designed around silicon plurality. The announcements convert the posture signaled by Oracle’s reported $300 billion OpenAI contract and 50,000-unit AMD MI450 commitment into an operating model in which Oracle owns the fabric and the data center shell while training, prefill, decode, and agent orchestration run on different vendors’ silicon. Futurum assesses that this is the clearest public blueprint yet for the multi-silicon AI cloud and that its economics turn on inference demand that no vendor has yet proven at this scale.
Inference Demand Breaks the Single Vendor Procurement Model
The deal stack maps onto the disaggregation of inference into stages with different silicon requirements. SambaNova’s pitch states the disaggregation thesis plainly. GPUs run prefill while the SN50 runs decode, the stage that sets agent response speed, with vendor claims of up to 5x the speed of competitive chips and 3x lower total cost of ownership in a 20 kW air-cooled rack. Cerebras specializes in the same decode stage on a wafer-scale part that keeps compute and memory on one die. Futurum’s 1H 2026 Data Center Semiconductors Market Sizing & Five-Year Forecast projects inference at 73% of data center AI accelerator demand in a market reaching $1,212.7 billion in CY2030, with agent and reasoning-first workloads at $546.0 billion. The implication is that a cloud selling tokens rather than GPU-hours can arbitrage architecture against workload. Oracle is the first hyperscaler to build that arbitrage into its public catalog.
Acceleron Moves Oracle’s Value from Reselling Chips to Owning the Fabric
Acceleron is where Oracle’s margin argument lives. Its custom SmartNIC lets Google TPUs keep their native ICI and optical circuit switch interconnects inside the pod while joining OCI storage and databases outside it, and making Oracle’s own fabric the common layer beneath every vendor’s silicon is the sharpest competitive signal of the day. NVIDIA Spectrum-X Ethernet, with Spectrum-6 switches and BlueField-4 DPUs, runs alongside Acceleron, and the multi-gigawatt Vera Rubin expansion keeps NVIDIA the anchor tenant of the buildout. AWS, Microsoft, and Google each pair merchant accelerators with first-party accelerators, while Oracle’s first-party silicon is the network. The open question is whether fabric ownership captures enough value to justify buying everyone else’s compute at market prices.
Agentic Workloads Return the CPU to the AI Factory Floor
Vera CPUs reached general availability with OpenAI bringing them into production for tool calls and code execution, and the planned Rubin HGX NVL8 pairs eight Rubin GPUs with two 64-core Intel Xeon 6 processors for x86-compatible AI serving. Intel’s multiyear agreement reads as roadmap and capacity coordination for this layer, with Diamond Rapids positioned for embedding generation, reranking, and the application services agents invoke. Futurum’s forecast places Intel at 45.3% of data center CPU value share in Q4 CY2025, with AMD at 29.7% and the Arm cohort at 25.0%, and agentic serving is where those shares will be contested. Agents spend most of their wall-clock time in tool execution, which returns the CPU to the center of AI infrastructure, and Oracle now sources CPUs from four suppliers at once: NVIDIA’s Vera, Intel’s Diamond Rapids, the AMD EPYC shapes OCI already runs, and Ampere’s Arm-based line.
Financing and Software Fragmentation Are the Costs of Plurality
The bear case is operational. Oracle has not said how it will finance the capacity, and NVIDIA CEO Jensen Huang has said Vera Rubin systems can generate up to $40 billion in revenue per gigawatt for NVIDIA, which prices the multi-gigawatt commitment in the tens of billions. Five silicon platforms mean separate demand forecasts and software stacks, and stranded capacity if agentic demand grows slower than the 73% inference share implies. CUDA, XLA, Cerebras’ SDK, and SambaNova’s dataflow stack do not share a developer, and making heterogeneity invisible falls on OCI’s scheduling and Kubernetes layers. The reported addition of OpenAI’s Broadcom-designed Jalapeño inference processor to OCI would add a sixth architecture. Oracle’s investor day this week should show whether revenue commitments attach to this capacity as they did with the OpenAI contract, because backlogs are not revenue.
What to Watch:
Whether Oracle discloses TPU, Cerebras, or SambaNova capacity commitments at its investor day this week
Whether Acceleron becomes the default fabric across the multi-gigawatt Vera Rubin expansion
Whether Cerebras and SambaNova publish OCI-validated tokens-per-second and cost benchmarks in 2027
Whether OCI X14 Diamond Rapids shapes reach general availability with AMX FP8 support in 2027
Whether Oracle RPO growth in fiscal Q2 2027 shows customers prepaying for non-NVIDIA capacity
Declaration of generative AI and AI-assisted technologies in the writing process: This content has been generated with the support of artificial intelligence technologies. Due to the fast pace of content creation and the continuous evolution of data and information, The Futurum Group and its analysts strive to ensure the accuracy and factual integrity of the information presented. However, the opinions and interpretations expressed in this content reflect those of the individual author/analyst. The Futurum Group makes no guarantees regarding the completeness, accuracy, or reliability of any information contained herein. Readers are encouraged to verify facts independently and consult relevant sources for further clarification.
Disclosure: Futurum is a research and advisory firm that engages or has engaged in research, analysis, and advisory services with many technology companies, including those mentioned in this article. The author does not hold any equity positions with any company mentioned in this article.
Analysis and opinions expressed herein are specific to the analyst individually and data and other information that might have been provided for validation, not those of Futurum as a whole.
Futurum Data Show Enterprises Moving Routine AI Work to Open Weights–Platform Vendors Capturing the Gains and Frontier Labs the Spending
What You Need to Know
Open Weights Reach Production: Open-weight models now run in production at 42% of enterprises in Futurum’s September 2026 drill-down (N=200), up from 31% in July. Production users expect open weights to carry 41% of their AI tokens within a year, up from 34% today.
Platform Vendors Take the Share: Google’s Gemma runs in 55% of production accounts, Microsoft’s Phi debuted at 39%, and NVIDIA’s Nemotron at 25%, while Meta’s Llama fell to 35% from 55%. Meta’s new Muse Spark Open will reach enterprises mostly through the same hyperscaler catalogs.
Origin Matters More: Country of origin is now a major or deciding factor for 47% of production users, up from 35%, and export-control exposure matters to 30%, up from 10%, as Chinese families lose ground in enterprise production.
Developers Move Faster, Toward Different Models: Open weights carry most tokens on the Vercel and OpenRouter gateways, led by Chinese models, yet take only a small share of the spending.
Frontier Labs Keep the Money: Open-weight models account for just 5% of enterprises’ metered AI consumption in Futurum’s October 2026 AI Tools Pulse, against 36% for Microsoft 365 Copilot and 29% for Claude, and in-house open-weight builds report the weakest ROI of any approach.
The Futurum View
Open-weight models have won the argument over whether enterprises will run them, so the more important question now is who profits. Our data suggest the answer is the companies that sell the infrastructure underneath the models. Google, Microsoft, and NVIDIA give their open models away to sell cloud capacity and chips, and enterprises are taking up the offer, while the frontier labs lose token share but keep most of the money. Meta’s return with Muse Spark Open in October 2026 is a serious attempt to break into that position, but the model reaches enterprises through the same hyperscaler catalogs, under a more restrictive license, with Meta’s best model still held back.
The move into production has happened faster than most enterprise buyers expected. In our September 2026 drill-down, 42% of 200 enterprises run open-weight models in production, up from 31% just two months earlier, and only 3% have never evaluated one. Our respondents are predominantly North American, so these figures describe the US market most closely. Among the 83 production users, open weights carry an average of 34% of AI tokens, against 23% a year ago, and those users expect 41% within 12 months. That works out to roughly half of each new token they consume. Most of that work is routine. Low-complexity workloads rose to 51% of production users’ open-weight use from 39%, and they are the high-volume tasks where agent loops consume the most tokens. We expect a split between cheaper workhorse models for routine work and premium frontier models for the hardest reason to become the standard enterprise architecture over the next year.
The Platform Vendors Take the Share
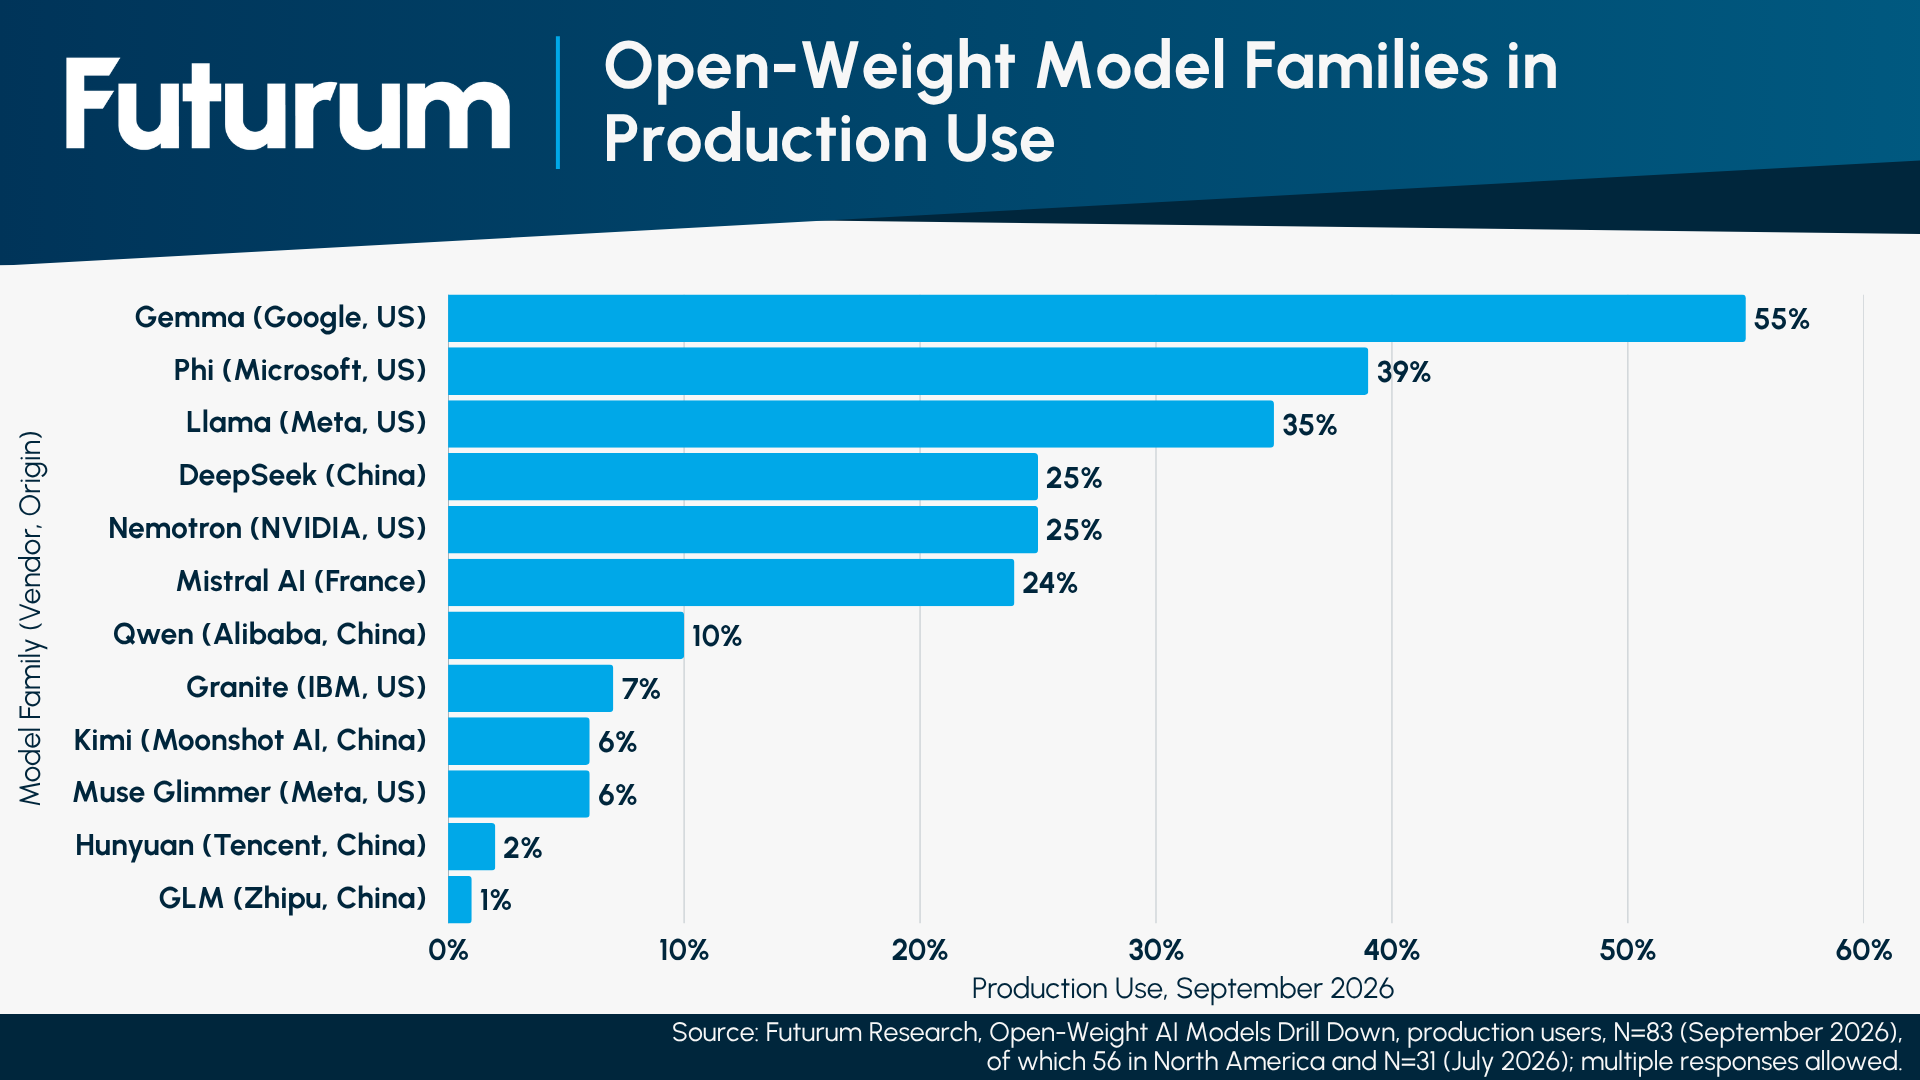
Google’s Gemma now runs in 55% of production accounts, up from 35%, while Microsoft’s Phi entered our list at 39% and NVIDIA’s Nemotron at 25% in their first survey cycle. Three of the five most-used families in production now come from companies that sell the cloud capacity or the chips those models run on, and each of them can afford to give a model away to win the infrastructure spending behind it. Meta’s Llama has paid the price. It led both the production and pilot groups in July, but now runs in 35% of production accounts, down from 55%. In our broader AI Product Series (N=511), more respondents have tried and dropped Llama (15%) than plan to keep using it (9%). Non-US families lost ground over the same period. DeepSeek fell to 25% of production accounts from 32%, Mistral to 24% from 32%, Alibaba’s Qwen to 10% from 13%, and Zhipu’s GLM to 1% from 10%, while Moonshot’s Kimi held at 6%.
Figure 1: Open-Weight Model Families in Production Use
Source: Futurum Research, Open-Weight AI Models Drill Down, production users, N=83 (September 2026), of which 56 in North America and N=31 (July 2026); multiple responses allowed.
Meta is now trying to regain that ground with a different model. Muse Spark Open is an 816-billion-parameter mixture-of-experts model built for coding and agentic work, derived from the Muse Spark model Meta kept proprietary at its April launch, and Meta describes it as the most capable open-weight model yet from a US lab. Our data predates the launch, but three details suggest that the platform vendors keep the advantage in the enterprise. Meta is distributing the weights through Amazon SageMaker, Google Cloud Model Garden, and Microsoft Foundry, so enterprise adoption will run through the hyperscalers’ catalogs. The Muse Model License carries limited commercial terms and a required product label, which will slow approval in enterprises where incomplete security and compliance reviews already hold up 62% of pilots. Meta has also kept its most capable model, Muse Wonder, proprietary. Like the frontier labs, Meta is opening its second tier and keeping its top tier closed.
The Frontier Labs Keep the Money
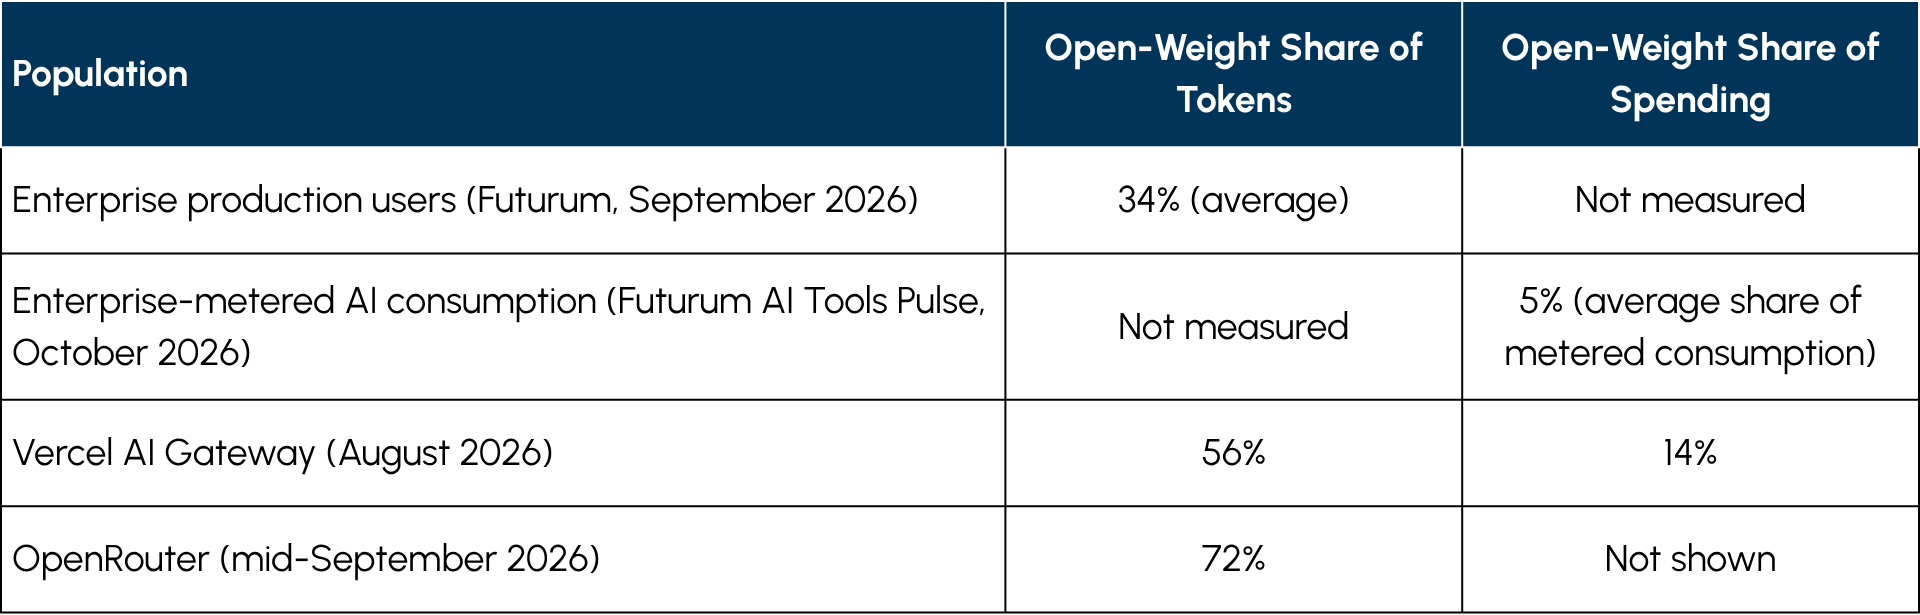
Developer traffic is moving faster still and toward different models. Two independent gateways show the same pattern. Vercel reported open-weight models handling 56% of token volume on its AI Gateway in August 2026, up from 13% in April, while taking only 14% of estimated gateway spending. OpenRouter reported that open-weight models carried 72% of its tokens in mid-September 2026, with Chinese labs alone accounting for 69%. Both platforms mainly serve developers and startups, so their data describes developer behavior rather than market share, and the volume is led by Chinese families such as DeepSeek, which hold a smaller share of enterprise production, where DeepSeek runs in 25% of accounts, down from 32% in July. Developers choose models largely on cost per token, while enterprises also weigh origin, compliance, and support, so the enterprise shift runs slower and favors different vendors.
Table 1: Open-Weight Share of AI Tokens and Spending
Source: Futurum Research – Open-Weight AI Models Drill Down, September 2026; Futurum AI Tools Pulse, October 2026 (N=100); Vercel AI Gateway Production Index, September 2026; OpenRouter, September 2026
Inside enterprises, the frontier labs face a smaller share of a larger pool, which is a more comfortable position than the headline shift suggests. Some 93% of production users say their proprietary usage is still growing. Asked how the two relate, 53% describe partial substitution, 40% call them complementary, and only 7% say proprietary usage has slowed or declined. The arithmetic supports the labs, too. If open weights rise from 34% to 41% of tokens, proprietary volume stays flat only if total usage grows by less than about 13%, and at 50% growth, proprietary volume still rises by roughly a third. The pressure shows up in price rather than volume. At performance parity, 66% of production users would move a workload for a discount of 25% or less, so the labs have every reason to cut prices before buyers move work elsewhere. Anthropic’s Opus 5.5, launched in September as a cheaper alternative to its Fable model, is an
early example.
Our October 2026 AI Tools Pulse (N=100) shows how little of the money has moved. Two-thirds of enterprises now use open-weight models in some form, up from 46% in August, yet open weights account for an average of only 5% of companies’ metered AI consumption, against 36% for Microsoft 365 Copilot, 29% for Claude, 15% for ChatGPT, and 10% for Gemini. Part of the gap is measurement, because self-hosted models generate no vendor bill, but that supports our argument. The token volume moving to open weights leaves the AI budget and reappears as infrastructure spending, which is where the platform vendors make their money. Substitution also remains shallow. On average, 47% of open-weight users report reduced use of each proprietary tool, a figure that has not moved in three months, and only 8% describe the reduction as significant. Hard limits are proving difficult as well, with only 22% of enterprises imposing them against the 41% that expected to by October, and shifting to cheaper models is the most-cited lever among those planning limits, at 58%.
The frontier labs also hold a capability lead at the top, although its size moves with each release cycle. On the Artificial Analysis Intelligence Index, which does not yet include Muse Spark Open, the best open-weight model trailed the leaders by about seven points six months ago and by about four points in July, according to Mozilla’s analysis, but the autumn frontier launches have pushed the gap back to 12 points, with 10 proprietary models now ahead of the best open one. The strongest open models are mostly Chinese, while the open families that enterprises run in production score far lower, with NVIDIA’s Nemotron 3 Ultra at 23 against 58 for the leading proprietary model. Meta’s new model narrows the distance for US open weights, although early comparisons show it trailing Kimi K3 and GLM 5.3 on agentic coding benchmarks. The hardest reasoning stays with frontier models, and 22% of production users would not switch at any price when an open model falls well short.
The Savings Come With Hidden Costs
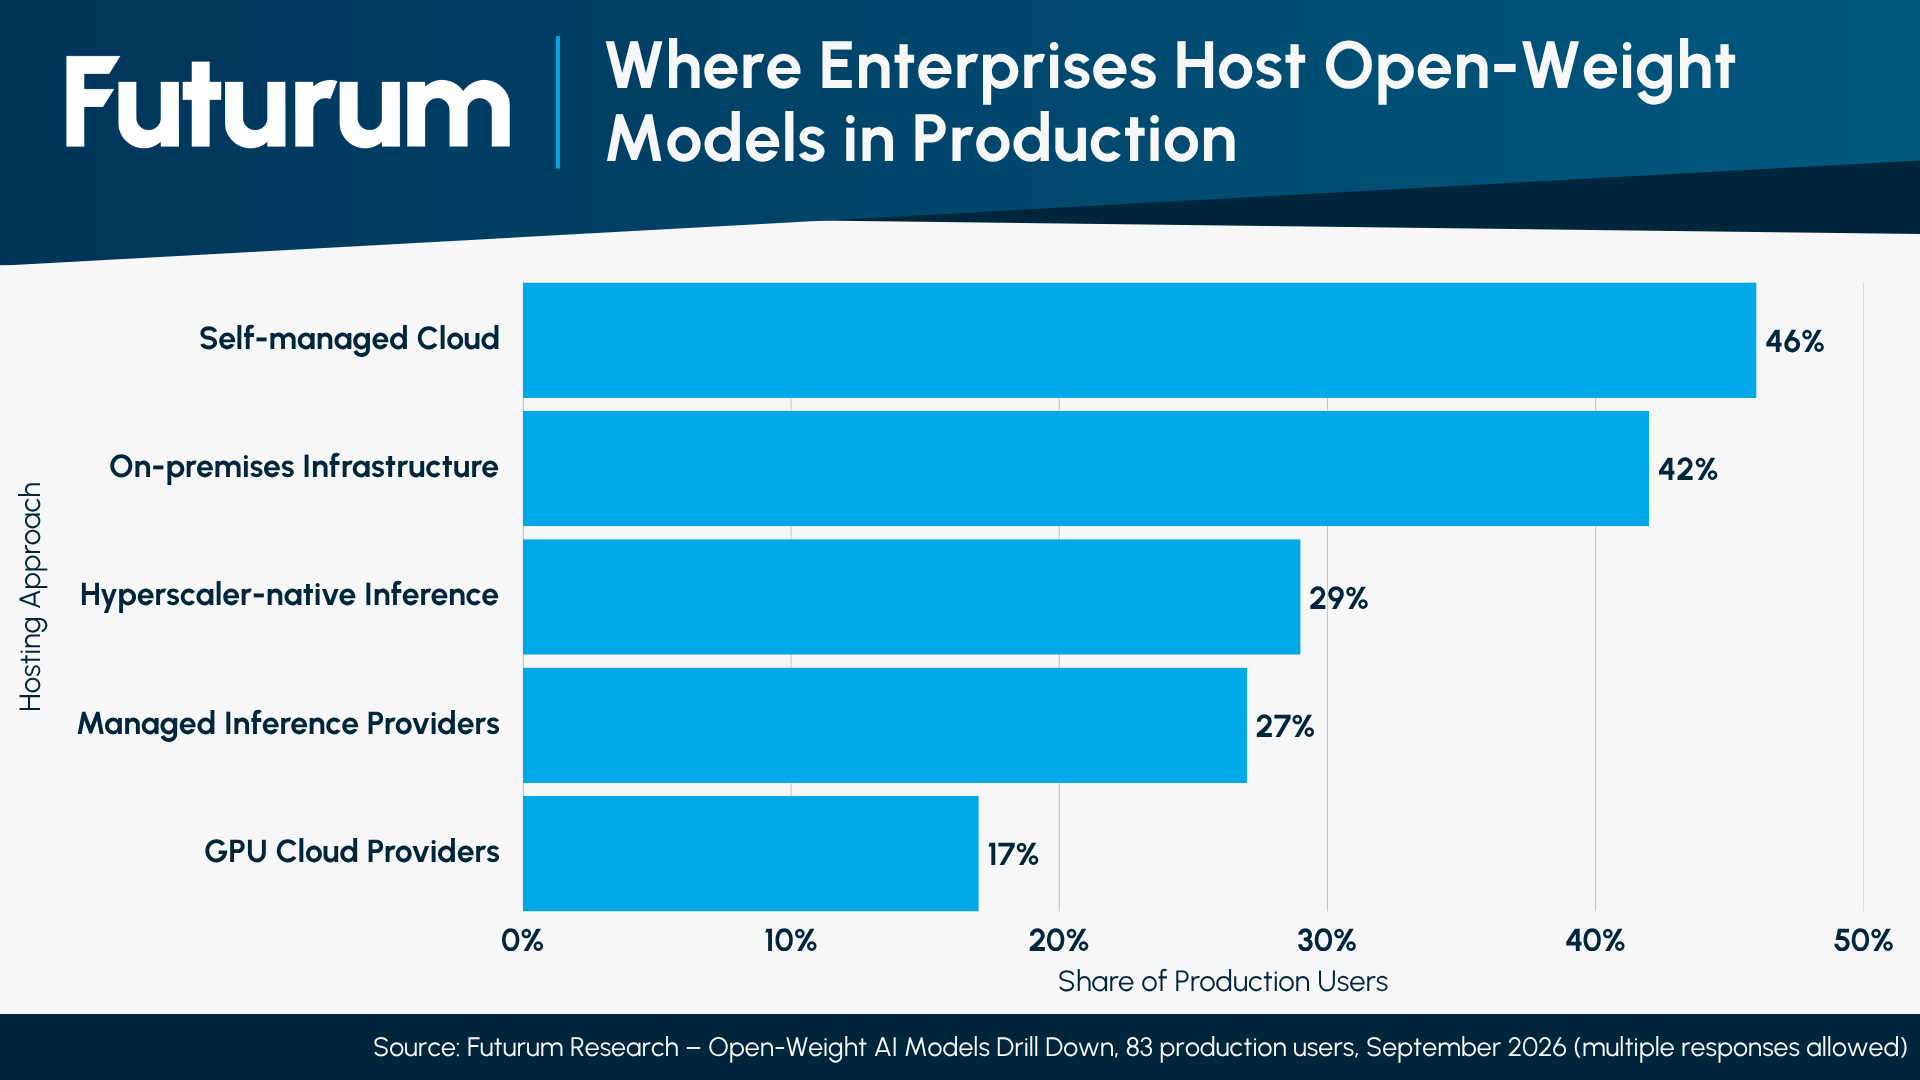
Enterprises should be realistic about where the savings go. Self-managed cloud (46%) and on-premises infrastructure (42%) lead production hosting, well ahead of hyperscaler-native inference (29%) and managed inference providers (27%). The cost leaves the token bill and reappears as servers, cloud compute, and engineering time. Self-hosting costs now hold up 50% of pilots, up from 40%. Our Macro Views survey adds a sharper warning. In-house open-weight builds report sustained ROI at scale in only 10% of cases, with 25% reporting no traction, against 17% at scale for external solutions, and 52% of non-users say they lack the self-hosting and fine-tuning skills required. For most enterprises, buying open weights through a platform will make more sense than building around them.
Figure 2: Where Enterprises Host Open-Weight Models in Production
Source: Futurum Research – Open-Weight AI Models Drill Down, 83 production users, September 2026 (multiple responses allowed)
The country-of-origin screen is also tightening. Origin is now a major or deciding factor for 47% of production users, up from 35%, and export-control exposure matters to 30%, up from 10%. Pilot use of Moonshot’s Kimi fell to 6% from 13%. Mistral, the most widely used European family, runs in 24% of production accounts, down from 32% in July, so it has yet to gain from the tighter origin screen. Buyers increasingly want open models from a jurisdiction they trust. That favors US vendors with US buyers, now including Meta, and could leave room for European providers with European buyers, provided they can match the platforms on hosting and support, although our largely North American sample cannot yet measure that.
And it should be noted that these numbers describe the leading edge rather than the whole market. Across the 511 enterprises in our AI Product Series, only 14% call open weights core to their AI strategy, and 26% rate open-weight availability as an important factor in model selection, up from 20% in March. The direction is clear, however. Open weights will become the default for routine, high-volume enterprise work, the frontier labs and Meta will keep their most capable models closed, and the value in open weights will accrue mainly to the vendors that sell the infrastructure underneath them.
What to Watch:
Muse Spark Open’s Enterprise Uptake: Whether enterprises adopt Meta’s new model despite its restricted license, and whether it lifts Meta’s open-weight position from Llama’s 18% Net Score, down 28 points year over year.
Frontier Repricing: Further price cuts, usage-commitment discounts, or seat-plus-consumption bundles from Anthropic, OpenAI, and Microsoft as they defend workloads within buyers’ 25% switching band.
The Capability Gap: Where Muse Spark Open lands on independent benchmarks, and whether US open models close any of the distance to the frontier or remain lower-cost models for routine work.
Developer and Enterprise Convergence: Whether enterprise open-weight token share moves toward the levels seen in developer gateways, and whether Chinese models gain any enterprise ground as they have with developers.
European Sovereign Providers: Whether the tightening origin screen creates room for European open-weight providers in EMEA, or whether US vendors’ hosting reach wins there too.
Self-Hosting Economics: Whether managed and hyperscaler-native inference options reduce the cost barrier holding up half of pilots, shifting open-weight work away from enterprise-owned infrastructure.
Disclosure: Futurum is a research and advisory firm that engages or has engaged in research, analysis, and advisory services with many technology companies, including those mentioned in this article. The author does not hold any equity positions with any company mentioned in this article.
Analysis and opinions expressed herein are specific to the analyst individually and data and other information that might have been provided for validation, not those of Futurum as a whole.
Oracle Corp. announced a significant expansion of its artificial intelligence (AI) cloud infrastructure on Tuesday, a multi-gigawatt partnership centered on NVIDIA Corp.’s Vera Rubin platform alongside a diversification push into hardware from Google, Cerebras Systems Inc., and SambaNova Systems Inc.
The announcements at Oracle’s annual AI World conference in Las Vegas underscore the company’s bid to establish Oracle Cloud Infrastructure (OCI) as an adaptable hub for the broader compute landscape.
Under the expanded alliance, Oracle will offer NVIDIA’s Vera Rubin NVL72 architectures and standalone Vera central processing units.
The integration of standalone CPUs addresses an emerging architectural bottleneck: while graphics processing units handle the heavy computational demands of training foundational models, agentic workflows require substantial CPU bandwidth to run tools, execute code, and retrieve database records. By decoupling CPU and GPU allocations, the companies aim to curtail idle hardware overhead.
However, Oracle is not relying solely on NVIDIA.
The cloud provider confirmed it will deploy its proprietary Acceleron networking chips within certain NVIDIA clusters, bypassing NVIDIA’s native networking components. In tandem, Oracle is opening OCI to external silicon, onboarding Alphabet’s Tensor Processing Units (TPUs) for the first time, as well as specialized inference hardware from Intel Corp.-backed SambaNova and Cerebras Systems.
“Different AI workloads have different compute needs,” said Mahesh Thiagarajan, president of Oracle Cloud Infrastructure. “That choice gives customers the flexibility to choose the right infrastructure for the performance, throughput, and economics of each AI workload.”
The inclusion of alternative processors targets the competitive inference segment, where systems execute trained models in response to direct user queries. While NVIDIA maintains near-total dominance over high-end training clusters, enterprise buyers have grown increasingly cost-conscious regarding ongoing operational deployments.
That shift coincides with mounting scrutiny over actual compute efficiency. Industry surveys from VentureBeat Intelligence reveal that nearly 80% of surveyed enterprise organizations report GPU utilization rates hovering at or below 50%.
For corporate customers, Oracle’s architectural flexibility presents an opportunity to address pipeline constraints such as data bottlenecks and CPU throttling without committing surplus capital to underutilized accelerators.
The aggressive buildout also comes as Wall Street reassesses the financial burden of the global AI infrastructure race. Oracle maintained an ambitious capital expenditure projection of $90 billion to $95 billion for fiscal 2027, noting that enterprise clients are increasingly funding dedicated silicon commitments directly.
Despite an initial lift during early conference trading, investor sentiment remains disciplined. Oracle shares have fallen more than 50% over the past 12 months amid persistent concerns regarding the capital intensity of cloud expansion.
Even bullish analysts have tempered expectations; ahead of Oracle’s analyst presentation on Wednesday, Wells Fargo affirmed an Overweight rating on the stock while trimming its price target from $280 to $250.
Oracle will present its comprehensive financial and infrastructure roadmap to Wall Street analysts on Wednesday.